If you are experiencing issues accessing Amazon Web Services (AWS) or a website hosted on their infrastructure, there is no single, global "Amazon server" that is down. Instead, AWS is a distributed network of independent regions and availability zones. To determine if an outage is affecting you, check the official AWS Health Dashboard, which provides real-time, region-specific status updates for every service in the Amazon ecosystem.
Understanding the Architecture of AWS Outages
To understand why "Amazon servers" are rarely entirely down, one must look at the structural design of cloud computing. Amazon Web Services does not operate as a single, monolithic data center. It is built upon the concept of Regions and Availability Zones (AZs).
A Region is a physical location around the world where Amazon clusters data centers. Within each region, there are multiple Availability Zones. Each AZ consists of one or more discrete data centers, each with redundant power, networking, and connectivity. Because of this architecture, an outage in one AZ in the "US East (N. Virginia)" region does not necessarily affect the "EU (Ireland)" region, nor does it necessarily impact other AZs within the same US East region.
When users report that "Amazon servers are down," they are usually experiencing a localized disruption in a specific region, or they are using a service that relies on a centralized control plane (the "brains" of the operation) that may be experiencing latency or error spikes. Rarely, if ever, does the entire global AWS infrastructure go offline.
How to Verify Current Service Status
If you suspect an outage, do not rely on anecdotal evidence from social media or third-party reports initially. Use the tools provided by Amazon to see if the issue is verified by their engineering teams.
- The AWS Health Dashboard: This is the authoritative source. Navigate to the AWS Health Dashboard. Here, you can view a comprehensive list of all AWS services categorized by region. Green checkmarks indicate nominal performance, while orange or red symbols indicate service disruptions or outages.
- Personal Health Dashboard: If you are a logged-in AWS customer, your Personal Health Dashboard is more precise. It identifies issues specifically affecting the resources you use in your own account. It provides deeper technical insights, such as specific incident IDs and resolution timelines, which the public dashboard may not display.
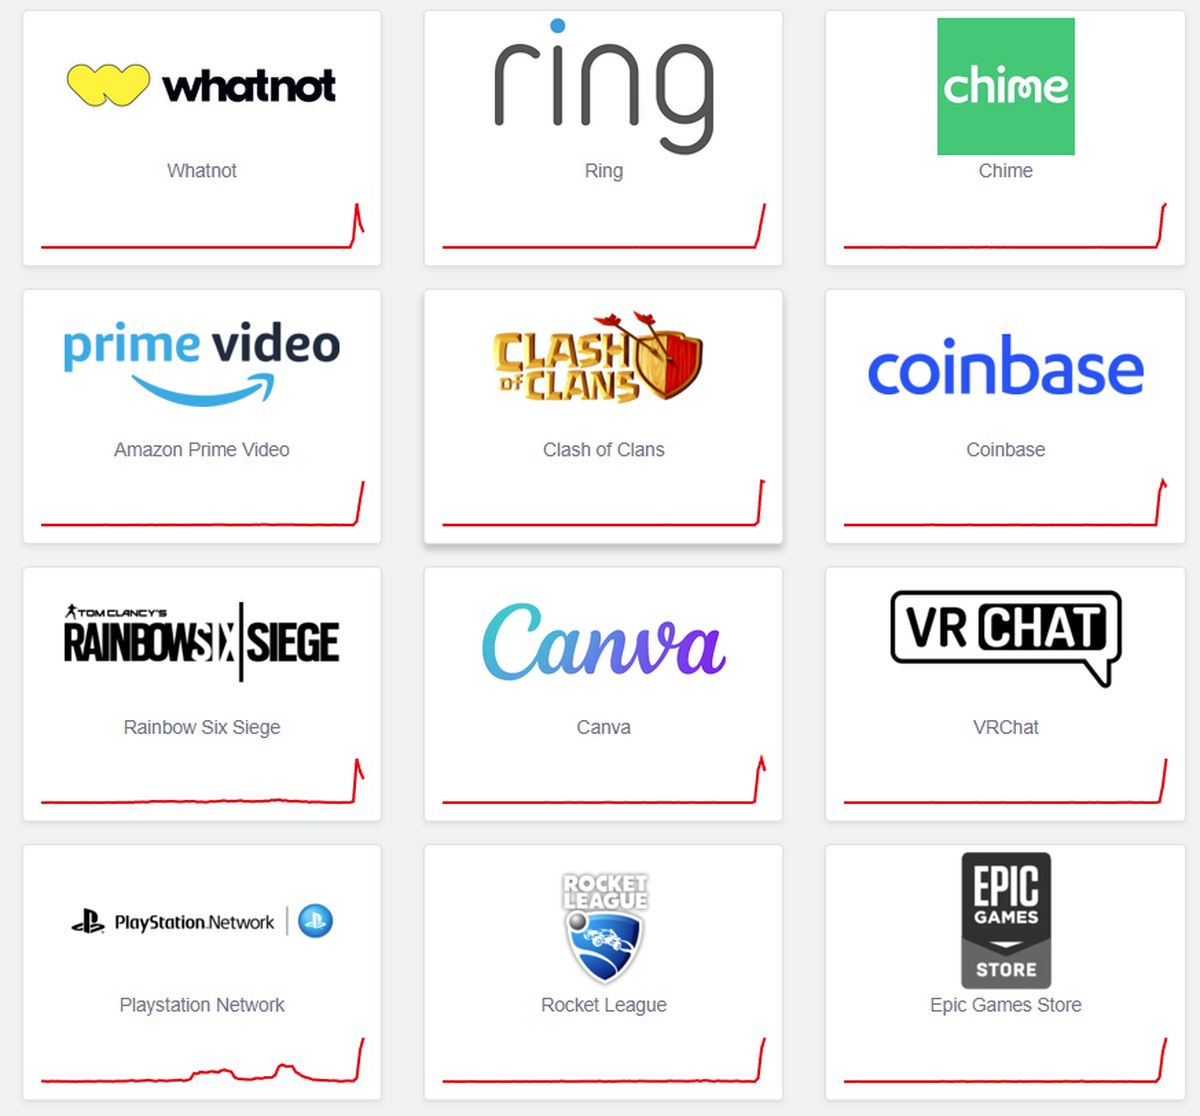
- Third-Party Monitors: Websites like DownDetector or similar service status aggregators rely on user reports. While these are excellent for gauging sentiment and confirming if others in your geographic area are experiencing similar issues, they are reactive and often imprecise. Use these to corroborate what you see on the official AWS dashboard, not as a replacement for it.
Distinguishing Between AWS Issues and Client-Side Problems
Before assuming the fault lies with Amazon, perform a quick triage to rule out local or ISP-related connectivity issues.
- DNS Resolution: If you can ping the IP address of an AWS-hosted server but cannot connect via its domain name (URL), the issue may be your DNS (Domain Name System) settings, not the server itself. Try switching to a public DNS resolver, such as 8.8.8.8 (Google) or 1.1.1.1 (Cloudflare), to see if the problem persists.
- ISP Throttling or Outage: Occasionally, your local Internet Service Provider may have routing issues that prevent your connection from reaching AWS data centers. Use a traceroute command (tracert on Windows, traceroute on macOS/Linux) to see where the connection drops. If it drops before reaching the AWS network, the issue is on your end or your ISP's end.
- Application-Specific Failures: Sometimes, the server is running, but the application code is failing. Check the error logs for your specific service. If you receive a 503 Service Unavailable or 504 Gateway Timeout, that is an indicator of server-side pressure. However, a 404 Not Found error typically suggests the server is fine, but the requested resource is missing or moved.
Common AWS Status Symbols Explained
When you view the AWS Health Dashboard, you will encounter a variety of statuses. Understanding these helps you manage your expectations for recovery:
| Status Symbol | Meaning | Action Recommended |
|---|---|---|
| Service is operating normally | No known issues detected. | Check your local network or application configuration. |
| Performance issues | The service is running but at reduced efficiency/speed. | Monitor your application performance; delay intensive tasks. |
| Service disruption | The service is experiencing an outage or severe degradation. | Implement your disaster recovery plan or wait for updates. |
| Information | Amazon is posting a notification regarding scheduled maintenance. | Review the notice for downtime windows and prepare accordingly. |
Impact on Managed Services vs. Infrastructure
It is vital to distinguish between Amazon’s managed services and the underlying infrastructure. If you host your own EC2 (Elastic Compute Cloud) instances, you are responsible for the guest operating system and the software running on top of it. If an EC2 instance crashes because of a software bug in your code, the "Amazon server" is technically fine, but your application is down.
Conversely, if an entire EBS (Elastic Block Store) volume in a specific region goes offline, that is an AWS-side issue. Most enterprise-level deployments include "multi-region" or "multi-AZ" redundancy. If your application is properly architected, a server failure in one zone should trigger an automatic failover to another, ensuring the end-user never notices that a physical server went down.
Steps to Take During a Verified Outage
If you have confirmed that AWS is indeed experiencing a service disruption in your region, follow these steps to protect your data and business continuity:
- Stop Pushing Updates: If the infrastructure is unstable, avoid deploying new code or making significant configuration changes to your environment, as this could corrupt data or create unrecoverable states.
- Enable Fallback Mechanisms: If you have a multi-region setup, manually trigger the DNS failover to shift traffic to a healthy region.
- Monitor Official Communications: Follow the official AWS support social media accounts or the status dashboard. Amazon engineers frequently update these channels with "Estimated Time to Resolution" (ETR) updates.
- Pause Automated Tasks: If your system relies on automated scripts to provision resources, these may fail repeatedly and incur unnecessary costs or trigger defensive security measures. Pause these until the service returns to a "Normal" status.
Frequently Asked Questions
Why does Amazon not just fix the server immediately? Amazon's infrastructure is massive. A "down" state often involves complex issues like network partition errors, power failure, or hardware degradation at scale. Fixing these requires isolating the faulty hardware to prevent cascading failures that could impact more customers.
Can I get a refund if AWS goes down? AWS offers Service Level Agreements (SLAs) for many of its services. If the availability falls below the guaranteed threshold (e.g., 99.99%), you may be eligible for service credits, which function as discounts on future bills. You must file a claim through the AWS Management Console once the incident is closed.
Does AWS have a phone number to call for outages? There is no public phone number to report general service outages. AWS support operates via a ticketed system in the AWS Support Center. If you have an Enterprise Support plan, you get access to faster response times and dedicated technical account managers who can provide updates during large-scale incidents.
What is the "Control Plane" and why does it matter? The control plane is the management layer of AWS. Even if your servers are running, if the control plane is down, you cannot change configurations, start new instances, or modify security groups. This is often what users mean when they say "AWS is down"—they cannot manage their environment.
How do I prevent my business from going down during an AWS outage? The primary defense is high availability architecture. This includes using Load Balancers to distribute traffic, distributing resources across multiple Availability Zones, and, for mission-critical apps, maintaining a "pilot light" or active-active setup in a secondary AWS region.
Next Steps for System Reliability
If you find that your business operations are frequently disrupted by regional AWS issues, you likely have a design deficiency rather than a vendor problem. In 2026, the standard for professional cloud operations is to assume that hardware will fail. Review your architecture against the AWS Well-Architected Framework, specifically the "Reliability" pillar. Implement health checks, automated recovery, and regional redundancy to ensure that your services remain operational regardless of the status of any single Amazon server.