In the context of server infrastructure and high-performance computing, "anal time" is an industry-recognized colloquialism referring to the precise, meticulous, and often exhaustive scrutiny of timing intervals, packet latency, and synchronization data. It denotes an engineering approach where microseconds or nanoseconds are analyzed with extreme rigor to identify bottlenecks in distributed systems, trading platforms, or real-time telemetry environments.
The optimization of server infrastructure requires a deep understanding of how time is measured, shared, and reconciled across hardware boundaries. When engineers speak of scrutinizing the "anal time" of a packet flow, they are referring to the extreme end of performance tuning, where the tolerance for jitter—the variation in latency—is near zero. This article explores the technical requirements, the importance of clock synchronization, and the methodologies for achieving micro-precision in modern data centers.
The Architecture of Temporal Precision
At the core of server infrastructure performance lies the ability to correlate events across multiple nodes. In a standard enterprise environment, system time is maintained via the Network Time Protocol (NTP). However, for mission-critical applications such as High-Frequency Trading (HFT) or synchronized distributed databases, NTP’s millisecond-level accuracy is insufficient.
Engineers must move toward the Precision Time Protocol (PTP), specifically IEEE 1588. PTP provides sub-microsecond accuracy, which is the baseline for what is colloquially termed "anal time" in professional infrastructure circles. Achieving this requires specialized hardware, including PTP-aware network switches and Grandmaster clocks equipped with Global Navigation Satellite System (GNSS) receivers.
Hardware Prerequisites for High-Resolution Timing
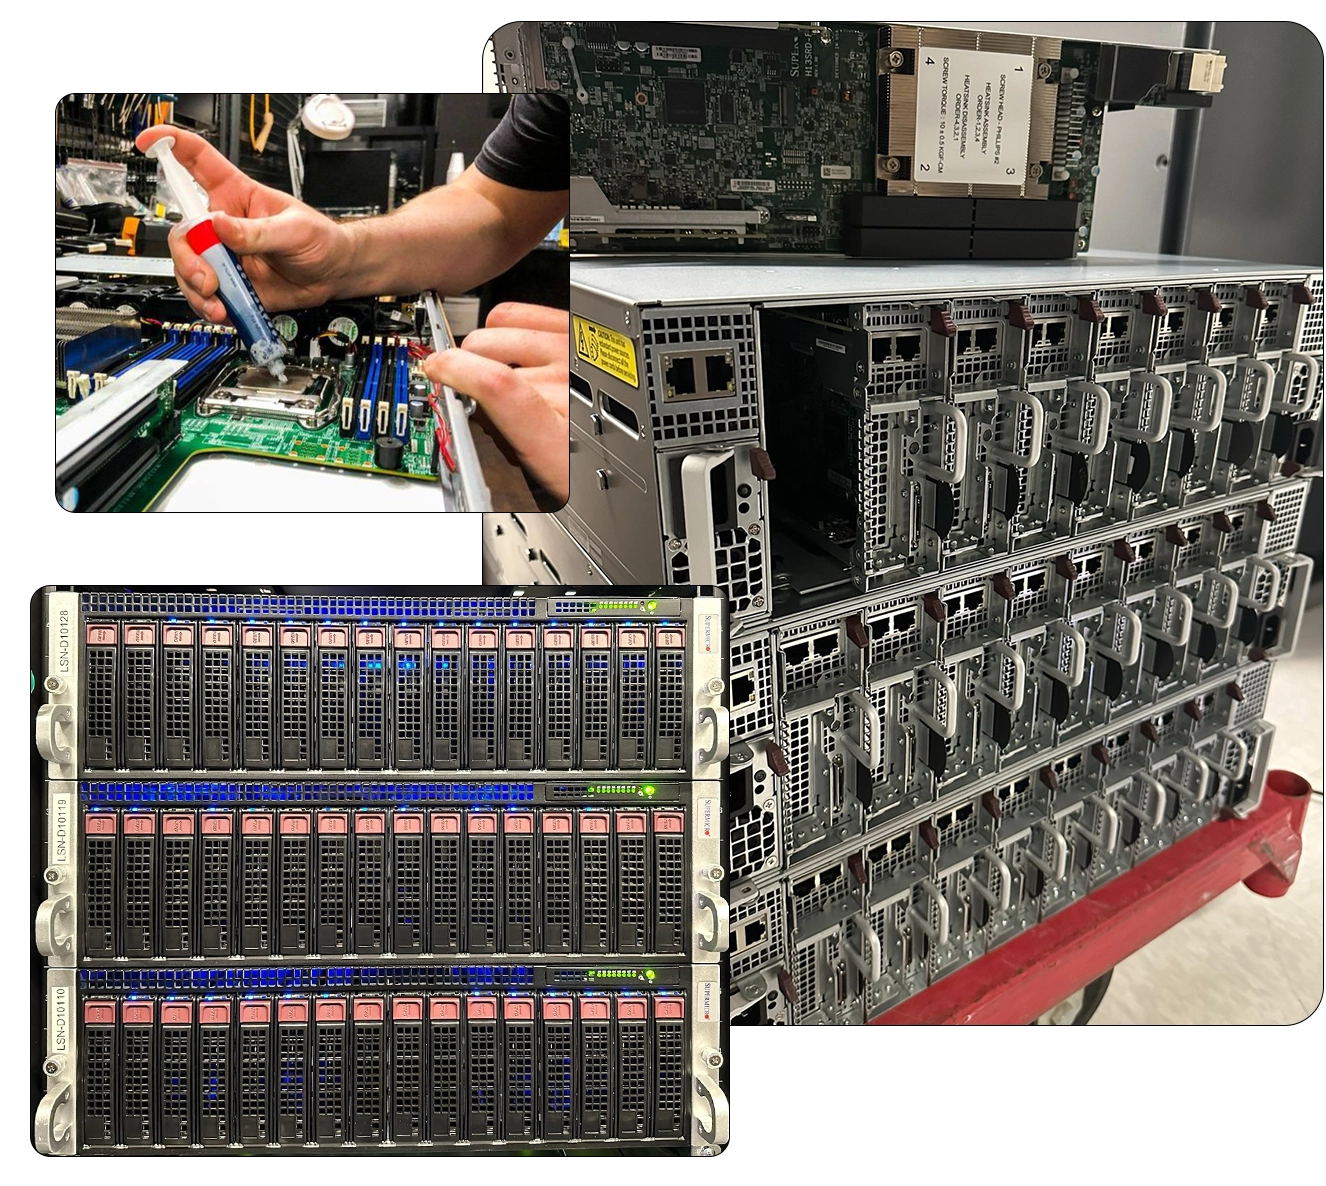
To perform the level of timing analysis described as "anal time," the server infrastructure must be equipped with specific components designed to minimize latency at every layer of the stack:
- NICs with Hardware Timestamping: Standard Network Interface Cards (NICs) often timestamp packets at the software layer (OS kernel). This introduces significant jitter. Precision-oriented infrastructure utilizes NICs that support hardware-level timestamping, moving the capture point to the physical layer (PHY).
- Atomic or GPS-Disciplined Oscillators: Local system clocks drift. An Oven-Controlled Crystal Oscillator (OCXO) or a Rubidium atomic clock provides the stable frequency necessary to keep the server in sync with the master clock, even if the primary synchronization source is momentarily lost.
- Kernel Bypass Technologies: Technologies such as Solarflare’s OpenOnload or DPDK (Data Plane Development Kit) allow applications to bypass the Linux kernel networking stack, reducing context switching and significantly tightening the latency distribution.
The Role of Jitter and Determinism
In infrastructure management, average latency is rarely the primary concern. The focus shifts to the "long tail" of latency distribution. When an engineer investigates these timing intervals with extreme rigor, they are looking for "outliers"—single packets that take 500 microseconds instead of 50.
These outliers are often the result of CPU power state transitions (C-states), interrupt coalescing, or System Management Mode (SMM) interrupts. Managing "anal time" involves pinning threads to specific CPU cores, disabling power-saving features in the BIOS/UEFI, and isolating IRQs (Interrupt Requests) to ensure that the processing environment remains entirely deterministic.
Comparison of Timing Methodologies
The following table compares standard administrative timing methods against high-precision infrastructure requirements.
| Metric | NTP (Network Time Protocol) | PTP (Precision Time Protocol) | Hardware-Accelerated PTP |
|---|---|---|---|
| Typical Accuracy | 1–10 Milliseconds | < 1 Microsecond | < 100 Nanoseconds |
| Primary Use Case | General IT, Logs | Distributed Systems | Trading, Real-time Control |
| HW Requirement | Standard Ethernet | PTP-Aware Switches | GNSS/Atomic Clock + PTP NIC |
| Complexity | Low | Moderate | High |
Troubleshooting Latency and Timing Inconsistencies
When you reach the stage of investigating these micro-intervals, traditional monitoring tools (like standard SNMP polling) will prove ineffective. The poll interval of a typical monitoring agent is usually 1 to 5 minutes, which is an eternity when analyzing sub-microsecond events.
To troubleshoot effectively, infrastructure engineers must employ:
- Packet Capture (PCAP) with Hardware Timestamps: Tools like
tcpdumpcan be configured to read hardware-level timestamps provided by the NIC. This allows for the capture of nanosecond-accurate packet traces. - Kernel Tracing (eBPF): Extended Berkeley Packet Filter (eBPF) allows for the observation of kernel-level events without modifying source code or stopping production processes. It is essential for identifying where timing drift occurs within the operating system.
- Core Isolation: Using the
isolcpuskernel parameter prevents the OS scheduler from placing general tasks on cores dedicated to high-performance packet processing.
Common Pitfalls in Temporal Tuning
A common mistake is the failure to account for physical cable length. In high-speed environments, signal propagation delay becomes a measurable variable. Light in fiber optic cables travels at roughly 2/3 the speed of light in a vacuum. At the nanosecond scale, the physical distance between a switch and a server can contribute to observable latency discrepancies that must be mathematically compensated for in the application logic.
Another frequent error is the assumption that virtualized environments can support "anal time" levels of precision. While SR-IOV (Single Root I/O Virtualization) brings performance closer to bare-metal, the hypervisor layer introduces inherent jitter that is notoriously difficult to eliminate entirely. For scenarios requiring peak temporal accuracy, bare-metal server deployment is almost always the required standard.
Security Considerations for Time Synchronization
Precision time is not merely a performance feature; it is a security necessity. In distributed systems, timestamps are used to prevent "replay attacks"—a type of network attack where an attacker intercepts a valid data transmission and retransmits it to trick a system. If the time windows for valid requests are not managed with extreme precision, the attack surface expands.
Furthermore, when logging events for security audits, inaccurate timestamps across servers make forensic analysis impossible. If Server A records an event at 10:00:00.001 and Server B records a correlated event at 10:00:00.005, but both actually occurred at the same time, the causal chain is destroyed. Infrastructure managers must ensure that PTP is authenticated and encrypted to prevent malicious actors from spoofing time signals, which could otherwise be used to manipulate synchronized system events or bypass security controls.
Future-Proofing for 2026 and Beyond
As of 2026, the industry is seeing a shift toward even more granular observability. The integration of programmable network switches (P4-programmable) allows for even tighter control over packet transit times. Infrastructure teams should prioritize:
- Standardization on White-Box Switching: Moving away from proprietary, "black box" hardware allows for better visibility into the internal clock synchronization mechanisms of the switch fabric.
- Automated Drift Remediation: Implementing scripts that continuously monitor the offset between the system clock and the Grandmaster, triggering alerts the moment drift exceeds a predefined threshold (e.g., > 50 nanoseconds).
- Observability Pipelines: Routing high-fidelity timing metrics into specialized time-series databases that can handle high-cardinality, high-frequency data ingestion without losing resolution.
Frequently Asked Questions
1. Why is standard network time not good enough for my infrastructure? Standard protocols like NTP are designed for distributed enterprise systems where a few milliseconds of jitter are acceptable. If you are operating in finance, real-time industrial automation, or high-performance scientific modeling, the cumulative drift in NTP can cause data collision, inconsistent ordering of transactions, and failed synchronization, leading to system-wide failures.
2. Can virtualization be used for high-precision timing requirements? While you can achieve high performance in virtual environments, you generally cannot achieve the "anal time" level of precision required for ultra-low latency. Virtualization introduces overhead due to the hypervisor’s mediation of hardware access. Bare-metal hardware remains the gold standard for nanosecond-level accuracy.
3. Does hardware-level timestamping increase CPU usage? No, it actually decreases it. By moving the timestamping responsibility from the CPU/Kernel to the NIC hardware, you free up compute cycles that would otherwise be spent on interrupt processing and kernel-stack management.
4. How do I verify my clock synchronization is accurate?
You should compare the local system time against a known-good Grandmaster clock using high-precision test equipment. Tools like phc2sys and ptp4l in the Linux PTP project are essential for monitoring the offset (the difference between your clock and the master) and the mean path delay (the time it takes for a packet to travel).
5. Is there a cost to maintaining this level of precision? Yes, both in terms of capital expenditure (CAPEX) for specialized hardware like PTP-capable switches and Rubidium clocks, and operational expenditure (OPEX) in terms of the expert staffing required to maintain such an environment. It is a niche, resource-intensive investment.
Final Recommendations for Implementation
If your infrastructure project requires this level of timing rigor, begin by establishing a baseline with a dedicated PTP monitoring tool. Do not attempt to tune the entire stack at once; instead, isolate a single network segment and replace standard hardware with PTP-capable components. Validate the synchronization offset under load—not just idle—because thermal changes and heavy CPU usage can induce jitter that is invisible during low-traffic periods. Finally, ensure that your monitoring system is configured to alert you not just on failure, but on the approach of your drift tolerance limits. Consistent observation is the only way to maintain the integrity of a high-precision temporal environment.